Resemble AI at a glance
Resemble AI is not currently taking new paying voice-generation customers. The company says it now focuses on multimodal deepfake detection and content verification; its historic voice customers remain supported and the open voice models remain available. This supersedes older articles describing it chiefly as an AI voice generator. [1][2]
Funding is company-reported; language count is for audio deepfake detection, not a claim that every voice-generation model speaks 54 languages. [3][6][11]
About Resemble AI
Resemble AI began as a company developing generative speech, speech-to-speech transformation and custom voice cloning for developers, games and media production. In its present form, Resemble AI, Inc. markets AI detection, identity matching, watermarking and forensic interpretation across media. A company that once made synthetic speech now primarily helps organizations identify synthetic or manipulated content. [1][2][12][13]
Its offerings are especially relevant to contact centers, identity and access teams, media verification, digital investigations, financial services and businesses safeguarding online transactions. Developers can integrate checks through APIs and official SDKs; enterprise customers can inquire about private and air-gapped deployments. [4][5][16][17]
Generate and transform voices
TTS, voice cloning, custom characters, multilingual speech, real-time pipelines.
Detect, verify and explain
Deepfake detection, identity, media provenance, agent detection and security workflows.
Key company facts
| Field | Verified information |
|---|---|
| Brand | Resemble AI |
| Legal entity | Resemble AI, Inc. (official Terms and Privacy Policy) |
| Founded | 2019 |
| Co-founders | Zohaib Ahmed; Saqib Muhammad |
| Current CEO | Zohaib Ahmed |
| Headquarters | US-based; LinkedIn lists Santa Clara, California; the privacy-policy mailing address is Mountain View, California |
| Historical roots | Toronto / McMaster / The Forge connections; historic listings vary by location |
| Company type | Privately held, venture-backed |
| Parent / acquisition | No verified parent or acquisition; appears independent |
| Ownership percentages | Not publicly disclosed |
| Current category | Enterprise deepfake detection, AI security, content authenticity |
| Former category | Generative voice AI, TTS, voice cloning, speech-to-speech |
| Current commercial voice sales | Closed to new customers, per CEO Aug 2026 |
| Main security products | Detect, Intelligence, Identity, Watermarker, Meetings, Agent Detection |
| Models | DETECT-World, RAD-S1, DETECT-3B Omni, DETECT-2B, PerTh, PerTh Multimodal, Resemblyzer |
| Open voice models | Chatterbox family, DramaBox and other research assets |
| Pricing | Flex usage-based; Team and Business subscriptions; custom Enterprise |
| Cumulative funding disclosed | US$25 million, company statement Dec 2025 |
| Valuation, revenue, profit | Not publicly disclosed / independently verified |
| Company size | LinkedIn 11–50; dynamic range, not audited headcount |
| Developer access | REST APIs, Python and Node.js SDKs |
| Deployment | Cloud API; enterprise on-premises / air-gapped |
| Official website | resemble.ai |
| Contact | support@resemble.ai · privacy@resemble.ai · security@resemble.ai |
Legal information: [12][13]. Company address and employee range: [12][31]. Status and products: [1][2][4].
Founders & leadership
Zohaib Ahmed · Co-founder & CEO
Ahmed co-founded the company in 2019 and remains its publicly identified chief executive in 2026. His earlier engineering experience included Magic Leap, Hipmunk and BlackBerry. A 2020 conference biography records a computer science degree from the University of Toronto. His 2026 founder statement explains why Resemble shifted from voice synthesis toward detection. [1][2][28][41]
Saqib Muhammad · Co-founder
Muhammad co-founded Resemble AI with Ahmed and was identified as chief operating officer in a 2023 investor announcement. His current executive title and day-to-day responsibilities could not be independently verified from a dated 2026 official leadership roster. Older professional profiles associate him with financial investment roles. [27][42]
| Person | Role and verification | Relevant evidence |
|---|---|---|
| Zohaib Ahmed | Co-founder & CEO, confirmed by Aug 2026 signed announcement | Engineering background: Magic Leap, Hipmunk, BlackBerry; University of Toronto degree |
| Saqib Muhammad | Co-founder, confirmed; COO historical as of 2023 | Gaming-origin founding; current title not publicly confirmed |
| Dev Shah | Head of Developer Relations, named in 29 Oct 2026 official publication | Author of RAD-S1 launch and technical explanation |
| Tedi Papajorgji | Third-party sources report technical/engineering leadership; current title unverified by official roster | Do not treat third-party CTO/VP title as confirmed current executive role |
The company has not published a complete independently verified 2026 C-suite and board directory in sources reviewed. COO, CTO, CPO and departmental leadership should not be invented.
Founding story & company history
According to its co-founders, studios could release game content faster than voice actors could record the corresponding dialogue. Resemble initially pursued the creation of adaptable digital voices to make spoken content easier to update. Its experience modeling synthetic speech later became a foundation for detecting impersonation and manipulated media as misuse increased. [1][2][28]
Founded by Ahmed and Muhammad
Initial focus: voice production for frequent game updates.
US$2M early financing / Resemble Clone
McMaster University reports investors and a new voice-cloning product.
The Andy Warhol Diaries
Synthetic voice recreated for the documentary with a voice-over production workflow.
US$8M Series A
Javelin-led round and growth of enterprise voice and Detect.
DETECT-2B and Identity / Audio Intelligence
Deepfake detection, multilingual and speaker identity added.
Chatterbox and PerTh open research
MIT-licensed voice model and watermarking tools.
T Challenge first prize
Recognition by Deutsche Telekom and T-Mobile US.
US$13M strategic financing
Company reported US$25M cumulative funding.
PerTh Multimodal / watermarking expansion
Audio, image, video and text provenance emphasis.
DETECT-World and full security pivot
CEO announced no new commercial voice customers.
JPFI and investigative case studies
Concrete evidence for forensic detection workflows.
RAD-S1 launched
Behavioral agent-versus-human detection on websites.
Sources: founding and policy pivot [1][2]; 2019 seed [29]; 2023 financing [27][28]; 2024 product releases [39][40]; 2026 launches [7][11][30].
Ownership, funding & investors
Resemble AI is a private independent company with venture and strategic backers. The company stated in December 2025 that it had raised US$25 million in venture funding to date. Summing three specifically itemized rounds (US$2M + US$8M + US$13M) produces US$23M; the remaining difference could involve other financing, but its precise composition is not publicly reconciled. Funding data providers disagree on later 2026 rounds; do not overwrite the company-disclosed cumulative figure with unverified totals. [3][27][28][29]
| Date | Round | Disclosed amount | Investors / lead | Verification |
|---|---|---|---|---|
| Dec 2019 | Early financing | $2M | Craft Ventures, Betaworks, AET Fund, firstminute Capital | McMaster University / The Forge |
| Jul 2023 | Series A | $8M | Led by Javelin Venture Partners; Craft Ventures, Ubiquity Ventures and Comcast Ventures | TechCrunch + Comcast Ventures |
| Dec 2025 | Strategic | $13M | Google AI Future Fund, Okta Ventures, Taiwania Capital, Gentree Fund, IAG Capital Partners, Berkeley Frontier Fund, KDDI and others | Resemble AI statement |
| Mar 2026 | Reported follow-on / strategic | Not publicly disclosed | Wa’ed Ventures mentioned in secondary funding databases | Third-party only; amount and terms unverified |
Ownership map: Co-founders + outside investors → Resemble AI, Inc. → detection, verification and watermarking products. A parent company or acquisition could not be verified. [1][3][13]
Current products & services
The active catalogue is an AI trust and security stack, not primarily a new-customer commercial voice-generator catalogue. Product names below are found on the current website and pricing page. [1][4][5][7][8][9]
| Product | Input | Output / purpose | Availability | Commercial model |
|---|---|---|---|---|
| Resemble Detect | Audio, image or video | Synthetic-media likelihood/verdict, modality metrics and evidence | Batch / file / streaming audio; cloud and enterprise on-prem | Usage-metered; API |
| Resemble Intelligence | Detection scores and supporting media | Human-readable forensic explanation / structured findings | Analysts, audit teams, compliance | Metered per second |
| Resemble Identity | Enrolled and incoming voice clips | Speaker match-distance and identity match candidates | Contact centers and KYC; 4-second enrollment minimum | Per identity search |
| Resemble Watermarker | Audio, image, video or text to mark / inspect | Embedded watermark and/or decode/provenance result | Publishing, enterprise compliance, IP protection | Encode / decode per call |
| Resemble Meetings | Zoom, Teams, Meet, Webex meeting audio/video | Live flags, notifications and forensic report | Meeting and recruitment security | Plan features + processing |
| Resemble Agent Detection / RAD-S1 | Browser interaction + environment signals | Visitor / AI-agent classification; client event | Website security / agent traffic governance | Per 1,000 sessions |
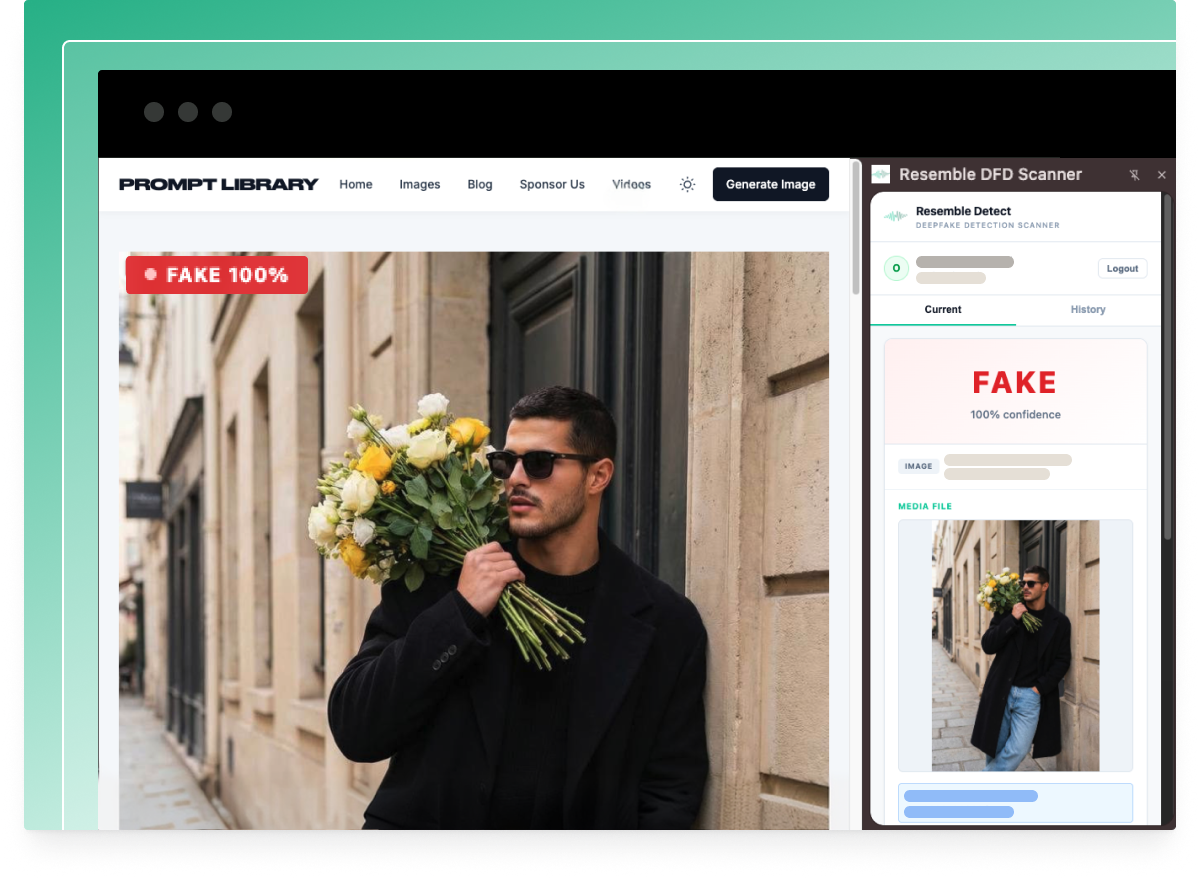
| Deepfake Detection Chrome Extension | Media encountered in browser | User-facing detection | Browser research / fact checking | Check product listing for access |
Detect
Deepfake classifier with audio, image and video support. Structured verdicts can be combined with Intelligence explanations.
Watermarker
Marks newly generated content and reads recoverable provenance marks; PerTh audio research remains open source.
Identity
Matches a questioned speaker against an enrolled voice, returning similarity/distance rather than proof of human authenticity by itself.
Agent Detection
New Oct 2026 detection for human-like browser automation using behavioral signals; not an audio product.
Historical commercial voice products
Resemble AI says its hosted voice generation services remain supported for existing customers only; no new commercial contracts are being sold. Its historical web product pages and live voice-related SDK examples must not be mistaken for a current offer to new buyers. [2][17][46]
| Former / research capability | What it did | Availability at research date |
|---|---|---|
| Text-to-speech | Turn written text into spoken audio using chosen synthetic or cloned voices | Legacy hosted contracts; open Chatterbox models available |
| Rapid / professional voice cloning | Create a voice representation from reference recordings; training requirements varied by model | Historical hosted offering; not generally sold to new clients |
| Speech-to-speech / voice conversion | Transform recorded performance into another target voice while retaining delivery elements | Legacy customer workflows / open source examples |
| Voice design | Generate new synthetic personas rather than duplicating an existing person | Historical feature; no confirmed new-client commercial path |
| Streaming voice / real-time agents | Deliver spoken replies to interactive systems | Historic commercial implementations; check existing contracts |
| Multilingual localization / dubbing | Adapt dialog or narration to different languages and voices | Historic customer use; open research varies by model |
| Chatterbox / Turbo / DramaBox | Open-source voice synthesis and expressive research models | Open/free under their applicable repository licences |
Do not reuse earlier Rapid Clone, Professional Clone or TTS per-second prices as if still offered for new Resemble commercial signups. [2][4]
How the technology works
These are simplified functional workflows. They do not imply that all products share a single architecture or that watermark detection and synthetic-media detection are interchangeable. [2][5][7][8][16]
Text-to-speech (historical/open)
Narration, accessible reading, game dialogue
Voice cloning (historical/open)
Character continuity, approved brand and performer voices
Speech-to-speech (historical)
Localization, dynamic game dialogue
Detect (current)
Fraud investigation, content moderation, media authenticity
Watermarker (current)
Content traceability and machine-readable origin
Identity (current)
Fraud and speaker verification
Voice cloning, text-to-speech & model architecture
Confirmed Resemble technologies
The public Chatterbox repository contains open voice synthesis inference code and model details; its README describes zero-shot conditioning on short reference voice samples, expressive controls and PerTh watermarking. Resemblyzer explicitly documents a 256-dimensional speaker embedding for comparing voices. PerTh publishes source for a neural audio watermarking method. These open projects demonstrate certain techniques, but they do not disclose the full internals of every former hosted voice model. [18][19][20]
| Technology | Purpose | Publicly confirmed? | Caution |
|---|---|---|---|
| Speaker embeddings | Numerical representations for speaker similarity | Yes — Resemblyzer open code | Not proof all production models use this exact encoder |
| Zero-shot / short-reference cloning | Condition speech on a reference speaker | Yes — Chatterbox research | Do not generalize requirements across past paid models |
| Expressive TTS | Control emotion/style parameters | Yes — Chatterbox | Control sets depend on model version |
| Neural watermarking | Inaudible in-signal trace of synthetic audio | Yes — PerTh project | Robustness differs with transformations |
| Transformers / autoregressive / diffusion | Possible architectures for speech generation | Only to the extent a specific repository discloses it | Do not infer from industry patterns |
| Hosted legacy proprietary architecture | Resemble past commercial voice engine | Not fully publicly disclosed | Undocumented details omitted |
Model training and datasets
Chatterbox public project material references approximately 0.5 million hours of cleaned training audio, but comprehensive source-by-source licensing, provenance and preprocessing documentation are not publicly established by the reviewed materials. The company’s current privacy policy says customer voice recordings are not used to train general-purpose models; that is a policy claim about customer data, not a complete list of all historical training sets. [12][18]
AI models, multilingual and real-time capability
| Model / family | Primary use | Status / access | Evidence |
|---|---|---|---|
| DETECT-World | Multimodal synthetic-media detection and physical-consistency checks | Current flagship proprietary model | [5][6] |
| DETECT-3B Omni | Earlier multimodal detection foundation | Current listed family / predecessor | [6] |
| DETECT-2B | Multilingual audio deepfake detection | Published 2024 predecessor | [40] |
| RAD-S1 | Browser visitor / AI-agent distinction | Launched Oct 29, 2026 | [11] |
| PerTh / PerTh Multimodal | Audio and multimodal watermarking | PerTh open-source; multimodal commercial | [7][19] |
| Resemblyzer | Speaker vector and similarity | Open-source Apache-2.0 repository | [20] |
| Chatterbox voice family | TTS / voice cloning / expressive audio | Open voice research; no new hosted commercial sales | [2][18] |
| DramaBox | Expressive TTS research | Open research model | [2] |
Language counts must be model-specific: DETECT-World officially cites 54 languages validated against MLAADv10 for audio detection. Resemble has published different language counts for older DETECT generations and Chatterbox variants. Do not treat a count for detection as a count for voice synthesis. [6][21]
Latency: DETECT is advertised for real-time or near-real-time security, with the company citing sub-300ms detection in one founder article; integration and media lengths affect observed timing. RAD-S1 separately claims server checks at a 120ms median and 200ms 95th percentile, measured for agent scoring rather than speech generation. The Crayola case study reports approximately 1–2 seconds per voice clip within a specific historical pipeline; it is not a general product SLA. [2][11][23]
Deepfake detection & benchmark evidence
Resemble Detect receives audio, image or video and returns a probabilistic assessment of synthetic generation/manipulation. DETECT-World combines artifact recognition with modeling of physical consistency (for example visual lighting and continuity). Intelligence adds more accessible explanations and structured reasoning. This may help an analyst investigate suspicious content, but detection by itself cannot establish malicious intent or guarantee authenticity. [5][6][10][16]
Benchmark classification: Podonos’s October 2026 public audio leaderboard includes DETECT-World scoring 99.47% accuracy on 4,524 audio clips; it appears fourth in the retrieved leaderboard rather than first, so claims of universal #1 performance are not supportable from this snapshot. Resemble’s video and image figures are company internal benchmarks pending external validation. The benchmark distribution and real-world prevalence of new generators, codecs, noisy calls or targeted attacks may differ. [6][32]
Measured performance must not be generalized to every language, all forms of edited media or every deployment. Its official privacy policy explicitly describes detection results as probabilistic and potentially producing false positives or false negatives. [12]
Audio watermarking, provenance & identity
PerTh embeds an imperceptible signal within audio and provides a decoder that looks for that mark after distribution. The enterprise-focused PerTh Multimodal extends watermarking workflows to image, video and text. The company describes compatibility with C2PA provenance records. A watermark can help attribute participating content, but a missing watermark does not prove a file is human-created, and a recoverable watermark does not necessarily prove every historical edit or owner claim. [7][19]
Detection
Predicts whether media appears synthetic — probabilistic classification.
Watermarking
Looks for an embedded mark added during a known production process.
Identity
Assesses similarity to an enrolled voice; does not alone establish the audio is live or unaltered.
Resemble Identity advertises a four-second minimum reference clip at a 16kHz sample rate for enrollment. This is not the same number as required source audio for older voice-cloning services. Combining Identity with Detect offers complementary checks: who the voice resembles and whether the content appears synthetic. [8]
API & developer platform
The current documentation details single-file detection, batch detection (up to 50 files per batch in the documented workflow), streaming audio detection, signed secure uploads, and optional watermark checks returned separately from the deepfake verdict. REST API paths and request syntax should be copied only from the live documentation. [16]
| Interface | Input | Output | Availability |
|---|---|---|---|
| Detect file / batch | HTTPS media URL or secure media token | Detection object with scores, modality metrics and artifacts | Current API |
| Streaming audio detection | Live audio stream | Per-window results; not persisted as Detect jobs | Current API |
| Resemble Identity | Enrolled speaker and candidate voice | Speaker match distance / search result | Current product / API |
| Watermarker encode / decode | Media asset and optional mark | Watermarked content or verification outcome | Current product / API |
| Intelligence | Detection result / linked media | Structured and readable rationale | Current API / metered |
| Agent Detection | Browser behavior samples | Session classification and client-side event | Current Oct 2026 product |
| Legacy TTS / voice endpoints | Text, reference voice, project | Synthesized audio | Existing contracts only |
Python SDK
Official Python library: pip install resemble. Current and historical methods are documented.
Node.js SDK
TypeScript-first library: npm install @resemble/node.
Other integration methods
REST/HTTP and documented workflow integrations; dedicated Unity / Unreal SDK status not independently established.
Cloud, on-premise & enterprise deployment
| Deployment option | Practical fit | Verification |
|---|---|---|
| Cloud SaaS and API | Teams building online verification workflows | Official current offer |
| On-premises containers | Enterprises requiring processing in their controlled environment | Official enterprise option |
| Air-gapped deployment | Restricted systems without external networking | Official enterprise claim |
| Microsoft Teams meeting integration | Meeting audio/video security | Official product / privacy policy |
| Zoom, Google Meet, Webex bot | Meetings security through calendar bot | Official product claim |
| Dedicated region / UK processing | Customer residency / regulated processing | UK region available on request per privacy policy |
| Private VPC / edge / device SDK | Specialized deployment | Not established as a standard publicly listed tier |
Vendor marketing asserts ISO and privacy alignment, but prospective regulated buyers should obtain the latest SOC 2 scope, ISO certificate, DPA, retention configuration and architecture diagrams for the exact product/deployment. [4][9][12][14]
Main use cases & industries served
| Workflow | User | Problem | Relevant product | Output / business use |
|---|---|---|---|---|
| Contact centers | Financial or telecom operator | Synthetic caller impersonates account holder | Detect + Identity | Escalate flagged calls to human verification |
| Media & publishing | Fact-checking / platform moderation | Edited political or public-interest audio and images | Detect + Intelligence | Prioritize content for editorial review |
| Digital forensics | Investigation firm | Disputed audio evidence may be AI-generated | Detect / forensic output | Document analytic signals and preserve human judgment |
| Financial onboarding | Bank or fintech | Fraudulent identity or altered evidence | Identity + Detect | Review KYC evidence and additional factors |
| Meetings & hiring | Enterprise security | Deepfake attendees in external meetings | Resemble Meetings | Warn moderators and verify identities |
| Content provenance | Media studio | Identify authorized media after distribution | Watermarker / C2PA | Attach and later check creation provenance |
| Gaming (historical) | Game studio | Dynamic lines and multilingual narration | Legacy TTS + S2S | Deliver character-consistent dialogue |
| Developers | SaaS or application team | Need automated classification in an app | REST API / SDK | Build automated screening with escalation |
| Website operations | Fraud / security lead | AI agents browsing like humans | RAD-S1 | Label, rate-limit or route agent sessions |
Current website positions detection for financial services, telecom, marketplaces, public-sector workflows, media, healthtech and software teams. Historical voice-generation case studies show gaming and entertainment usage; these should be flagged as past implementations rather than new-customer voice offers. [1][5][23][24]
Customers & documented implementations
| Organization | Relationship class | Use case / product | Reported result and caveat |
|---|---|---|---|
| RED Games / Crayola Adventures | Official detailed case study | Legacy speech-to-speech + TTS for dynamic game narration in 13 languages | Resemble-reported 26M generated lines; 22,000 hours of audio; case-specific metrics |
| JP French International | Named current detection case study | Resemble Detect for disputed forensic recordings | Experts describe faster screening and better documented investigations; no externally audited savings metric |
| Netflix / The Andy Warhol Diaries | Official named media case study | Historic synthetic voice reconstruction for documentary narration | Implementation confirmed in Resemble case study; voice rights approval terms not fully evidenced |
| Fabler | Official named historical case study | Parent voice cloning for personalized child storytelling | Resemble reported 100+ voices cloned; case-specific, not global platform metric |
| Deutsche Telekom / T-Mobile US | Competition + disclosed ongoing relationship | Detection / telco security collaboration | 2025 T Challenge award; not proof of every rumored deployment |
| Telnyx | Public customer/partner testimonial | Network identity and call security collaboration | Named testimonial; deployment scope not fully disclosed |
| Global investigations firm (unnamed) | Anonymous official case study | Detect and Intelligence for forensic audio evidence | Customer identity deliberately withheld; do not invent a name |
Selected case studies
Crayola Adventures / RED Games
Problem: Narrate arbitrary words supplied by children without breaking character continuity.
Solution: Historical custom TTS + two speech-to-speech stages in a dedicated pipeline. The May 2026 case study reports 13 languages and 26 million generated lines. These figures reflect that implementation, not platform-wide reach. {ref(23)}
JP French International
Problem: Forensic specialists needed a documented way to investigate whether disputed speech might be AI-generated.
Solution: Detection screening before conventional speaker comparison, with human corroboration and court-discussable reports. No guaranteed legal outcome is claimed. {ref(24)}
The Andy Warhol Diaries
Problem: Narrate the subject’s writing in a voice associated with Andy Warhol.
Solution: Resemble-generated voice used in the documentary, paired with human voice-over performance. Do not infer voice-owner consent procedure from this public account. {ref(25)}
Fabler
Problem: Personalized bedtime stories in a parent’s voice.
Solution: Reference recordings plus Resemble API voice output. The company reports more than 100 cloned voices in the project. {ref(26)}
Partnerships, integrations & programs
| Entity | Relationship | Evidence / status |
|---|---|---|
| Javelin Venture Partners / Comcast Ventures / Craft Ventures / Ubiquity Ventures | Investors (not automatically customers) | Series A reporting and investor statements |
| Google AI Future Fund / Okta Ventures / Taiwania Capital / others | Strategic financing participants | Company’s Dec 2025 announcement |
| Deutsche Telekom / T-Mobile US | T Challenge + stated ongoing partnership | Official press page; commercial scope not fully itemized |
| Telnyx | Telecom technology collaboration | Public testimonial and company technical commentary |
| Microsoft Teams | Native meeting integration | Current meeting product and privacy policy |
| Zoom / Google Meet / Webex | Meeting-bot support | Product page (platform coverage is vendor-reported) |
| C2PA | Content provenance standard compatibility | Watermarker product pages |
| The Forge / McMaster University | Historic accelerator / incubator | 2019 incubator history |
| Betaworks Synthetic Camp | Historic accelerator participation | Founder podcast/profile reporting |
| Y Combinator / Techstars | Participation not verified | Not publicly verified from sources reviewed |
Current developer documentation directly confirms official Python and Node.js SDKs. Claims that Resemble provides dedicated, maintained native Unity, Unreal, iOS or Android SDKs require separate verification; the ability to call an HTTP API is not proof of native integration. [17][27][29][30][41]
Pricing checked: 31 October 2026
The public pricing page is now headed Deepfake Detection & AI Security Pricing. Its plans are usage-metered detection services rather than public pricing for new voice-generation customers. The no-subscription Flex tier does not mean all processing is free; users buy credits for chargeable calls. [2][4]
| Plan | Subscription | Key access | Representative listed rates | Best for |
|---|---|---|---|---|
| Flex | $0 monthly subscription | 1 seat; credits purchased as needed | Audio Detect $0.035/sec; video $0.07/sec; image $0.035 | Developers evaluating detection |
| Team | $350/month or $280/month billed annually | 5 seats; batch and large uploads | Audio $0.015/sec; video $0.03/sec; image $0.015 | Growing operational teams |
| Business | $1,000/month or $800/month billed annually | 20 seats; SSO; org calendar options | Same listed audio/video/image volume bands as Team | Multi-team deployments |
| Enterprise | Custom / Contact Sales | SLAs, custom models, support, on-prem | Volume-negotiated | Large or regulated deployments |
| Meter | Flex | Team / Business |
|---|---|---|
| Audio deepfake detection | $0.035 / second | $0.015 / second |
| Image detection | $0.035 / image | $0.015 / image |
| Video detection | $0.070 / second | $0.030 / second |
| Resemble Intelligence | $0.025 / second | $0.015 / second |
| Identity search | $0.00050 / call | $0.00050 / call |
| Watermarker encode | $0.00050 / call | $0.00050 / call |
| Watermarker decode | $0.00020 / call | $0.00020 / call |
| Agent Detection | $1 / 1,000 sessions | $1 / 1,000 sessions |
USD published list rates; sales tax, usage minima, enterprise commitments and API limits may differ. Checked directly against Resemble AI’s pricing page on 31 October 2026. The last section of the profile links to the live pricing URL for publication-day rechecking. [4]
Business model & market traction
Confirmed revenue model: self-service detection API credits, Team and Business platform subscriptions, usage billing for media processing, identity searches, watermark operations and agent sessions, and customized enterprise contracts for support, deployment and higher-volume terms. The company’s funding statement also indicates a strategic distribution approach through investors that integrate its technology. [3][4]
Not independently established: the share of revenue from legacy voice customers, total recurring revenue, audited customer counts, paid-to-free conversion, historical profitability and the contribution of each product. A company-operated site has cited millions of users; that is a company marketing figure and is not equated here to active paying customers. [3]
Privacy, consent & voice rights
The August 14, 2026 privacy policy gives unusually specific processing terms. It says Resemble acts as a processor for its business customers’ voice and detection workloads, while acting as controller for account operations, marketing, billing and its consent-verification activities. Customer voice recordings and models are used to deliver the contracted voice service; the policy states that they are not used to train shared general-purpose models. [12]
| Topic | Policy-confirmed statement | Critical context |
|---|---|---|
| Voice samples / models | Retained while associated account remains active; 30-day grace period after termination or deletion request | Subject to law/contract exceptions in full policy |
| TTS inputs and outputs | Text and delivered synthesized audio are not retained after delivery | Current written policy; legacy service scope persists |
| Detection media | Deleted after analysis unless flagged | Flagged files and results have separate retention rules |
| Meeting media | Unflagged media analyzed and discarded; flagged media retained per customer instruction within policy limits | Customer must meet notice/consent requirements |
| Biometric identifiers | Deleted when purpose ends and no later than 3 years except as required by law | Voice/facial data is sensitive |
| International processing | Main US regions and subprocessors are named; UK region on request | Obtain DPA and SCC details |
| Consent verification | Recorded spoken consent may be required before a cloned voice is created | Appeal/human review process is described |
| Training customer voice data | Policy says no shared general-purpose training | Not a full audit of all model training sources |
For the current security products, the company’s ethics policy prohibits unconsented enrollment, unlawful surveillance, discriminatory profiling and misrepresentation of detection results. The Terms caution against using a probabilistic result as the sole basis for an adverse decision. [12][13][15]
Enterprise security & responsible AI
The public trust center identifies ISO/IEC 27001:2022 certification and completion of a SOC 2 Type II examination for Security, Availability and Confidentiality; supporting documents may require access or a request. The website also describes GDPR and HIPAA programs. Those are vendor representations; regulated buyers should review the actual attestation scope. HIPAA is not a general government certification. [14]
The privacy policy describes TLS 1.2+ encryption in transit, AES-256 at rest, the use of named subprocessors and data rights channels. Security and privacy controls do not make a detector infallible. An analyst should combine outputs with evidence provenance, independent review, identity checks and a documented escalation policy. [12][14][15]
Prevent misuse
Authorized voice consent and access controls.
Detect content
Multimodal detection and evidence assessment.
Prove provenance
Recoverable watermark and signed provenance workflows.
Reviews & reputation
Historic voice-product reviews do not necessarily measure the 2026 security platform. G2’s public listing shows a small sample and discusses voice quality, integration, pricing, pronunciation and usability; Trustpilot reviews include some critical feedback about charges, support and generation errors. Such comments are user sentiment, not independently verified operational failure rates, and many concern the earlier voice product. [33][34]
On the positive evidence side, Resemble has an official 2025 T Challenge award and published 2026 detection customer accounts. These claims should be interpreted in their own contexts rather than as a universal independent ranking of every tool. [24][30]
Competitor landscape
The competitor set changes depending on whether the buyer needs new speech generation or present-day synthetic-media security. Voice TTS companies are historical category peers; deepfake verification vendors are more direct current commercial competitors.
| Platform | Category | TTS / cloning | Deepfake detection | Current comparison relevance |
|---|---|---|---|---|
| Resemble AI | AI security + open voice research | Open models; legacy paid product | Yes: audio, image, video | Subject company; no new paid hosted voice signups |
| ElevenLabs | Generative voice API | Yes | Not established as matching enterprise multimodal detection suite | Strong new voice-generation alternative |
| Cartesia | Real-time voice API | Yes | Not established here | Real-time voice-generation alternative |
| Respeecher | Voice conversion and entertainment | Yes | Not established here | Historic creative voice workflow peer |
| Microsoft Azure AI Speech | Cloud speech platform | Yes; custom voice access controls | Different enterprise security portfolio | Cloud speech procurement comparison |
| Google Cloud TTS | Cloud speech platform | Yes; features vary | Different enterprise security portfolio | Cloud speech procurement comparison |
| Amazon Polly | Cloud TTS | Yes; custom voice conditions vary | Different enterprise security portfolio | Cloud speech procurement comparison |
| Pindrop | Voice and fraud security | Not core positioning | Yes, fraud/voice security | Current security competitor |
| Reality Defender | Multimodal detection | Not core positioning | Yes: audio, image, video | Current security competitor |
| PlayHT / PlayAI | Historical voice provider | Formerly yes | No reliable current offer | Reported shutdown; not a verified live purchasing option |
This is a capability/positioning comparison, not a head-to-head controlled benchmark. Features and access change. Sources for Resemble [2][4], ElevenLabs [35], Reality Defender [36] and PlayHT status [44].
Resemble AI vs alternatives
vs ElevenLabs
Choose ElevenLabs to evaluate a commercially available hosted TTS/voice-cloning API. Choose Resemble to evaluate multimodal detection, watermarking or voice identity. Both have research/voice heritage, but the companies now sell into different main requirements. No all-purpose quality winner can be inferred. {ref(2,35)}
vs PlayHT
PlayHT/PlayAI was historically another API-first voice synthesis option. Public reporting indicates it was unavailable/discontinued in 2026, making current feature and pricing comparisons largely historical rather than two active subscription choices. {ref(44)}
vs Cartesia / Respeecher
Cartesia focuses on speech generation for low-latency agents; Respeecher has voice-conversion and entertainment heritage. Their creative voice offerings are more relevant for a new synthetic voice purchase than Resemble’s closed-to-new-buyers commercial voice products. Compare licences, performer permission and live latency on a project basis.
vs Pindrop / Reality Defender
These are more direct 2026 detection/security comparisons. Evaluate modality coverage, false-positive rates on your own data, telephony codecs, deployment, audit evidence, pricing and regional controls. Do not rank providers globally from isolated vendor benchmarks. {ref(32,36)}
Strengths, limitations & suitability
| Evidence-based strength | Qualification / limitation |
|---|---|
| Current multimodal detection and explainability | False positives and unseen attack distributions still require human review |
| Watermarking and identification in the same vendor stack | A missing watermark does not prove authenticity |
| Public SDKs, API, batch and streaming workflows | Integration and processing costs rise with media volume |
| On-premise and air-gapped options | Enterprise contract and implementation required |
| Open voice research with MIT-licensed projects | No new commercial voice-generation subscriptions |
| Documented consent and privacy policies | Customer must meet its own legal/privacy obligations |
| Named case studies in forensics and gaming | Historic voice outcomes cannot be generalized to security deployments |
Best for: security leaders, digital-forensic analysts, trust-and-safety teams, banks, media investigators, telecoms, and developers integrating synthetic-media risk screening.
Less suitable for: new customers primarily seeking a hosted voice-cloning service; teams expecting zero false positives; anyone trying to clone a speaker without permission; and organizations needing compliance guarantees without reviewing the contract and attestation evidence. [2][12][16]
Frequently asked questions
What is Resemble AI?
A private US-based AI company originally known for generating synthetic voices and now focused commercially on detecting and verifying synthetic media.
Who founded Resemble AI?
Zohaib Ahmed and Saqib Muhammad founded Resemble AI in 2019.
Who is the CEO?
Co-founder Zohaib Ahmed is named CEO in the August 2026 strategy announcement.
Where is Resemble AI headquartered?
Its current LinkedIn page lists Santa Clara, California. Its August 2026 privacy policy gives a legal mailing address in Mountain View, California; these are distinct fields.
What is Resemble AI’s legal entity?
Its official Terms and Privacy Policy identify Resemble AI, Inc.
Is Resemble AI private or public?
It is privately held; there is no public stock listing established by this research.
Does Resemble AI still sell paid voice generation?
Not to new customers, according to the company’s August 13, 2026 announcement. Existing voice customers continue to receive support.
Are Resemble AI voice models still available?
Its open voice research models, including Chatterbox, remain available in public repositories subject to their individual licences.
Does Resemble AI offer voice cloning?
It built commercial voice-cloning technology historically, and open Chatterbox models can condition speech on reference audio. Do not assume new hosted paid accounts can be opened.
How much audio is needed to clone a voice?
There is no single current Resemble commercial requirement for new customers. Open model reference length depends on model; the separate four-second Resemble Identity minimum is for verification, not cloning.
Does Resemble AI support text-to-speech?
Yes in its open research and historical hosted service, but it is not accepting new commercial hosted voice buyers.
What is speech-to-speech?
A transformation of an existing speech performance into another synthetic voice, distinct from producing speech directly from text.
Can Resemble AI detect AI-generated speech?
Yes. Resemble Detect evaluates audio and returns a probabilistic classification and supporting metrics.
Can Resemble AI detect manipulated video and images?
Yes, the current DETECT-World offering covers audio, image and video.
Does Resemble AI guarantee every fake is caught?
No. Its own policies acknowledge false positives and false negatives; detection scores are not definitive proof.
What is DETECT-World?
Resemble’s current flagship multimodal detection model, described as combining known artifact detection with physical-consistency analysis.
What is RAD-S1?
A model introduced October 29, 2026, for distinguishing human website visitors from computer-use agents and automation.
What is PerTh?
An open audio watermarking project that embeds an imperceptible signal and provides tools to test for it.
Does watermarking prove a piece of content is genuine?
Not by itself. A recovered mark can provide provenance in a participating workflow; its absence or presence is not universal proof of authenticity.
How many languages does Resemble AI support?
The company cites 54 languages for DETECT-World detection validation. Voice-generation language support varies by open model and historical product.
Does Resemble AI have an API?
Yes. Its official developer documentation describes detection APIs, secure upload, batch workflows, and streaming audio checks.
Which SDKs are officially documented?
Python and Node.js are explicitly documented as official client libraries.
Does Resemble AI offer on-premises deployment?
Yes, it advertises enterprise on-premises and air-gapped deployment, subject to enterprise terms.
How much does Resemble AI cost?
As of October 31, 2026: Flex is $0 subscription plus metered credits, Team $350 monthly or $280 per month paid annually, Business $1,000 monthly or $800 annually, and Enterprise is custom.
How much funding has Resemble AI raised?
The company reported $25 million cumulative venture funding in December 2025. Secondary databases have inconsistent later figures.
What is Resemble AI’s valuation?
Current valuation is not publicly disclosed in the primary sources reviewed.
Who uses Resemble AI?
Named documented examples include RED Games (historic voice), JP French International (detection), Fabler (historic voice), and a Resemble case study involving Netflix’s The Andy Warhol Diaries.
Does Resemble AI require voice-owner consent?
The privacy policy describes a recorded consent-verification workflow for voice cloning, and its ethics policy prohibits unconsented enrollment.
Does Resemble AI train public models on customer voices?
Its August 2026 privacy policy states that customer voice recordings and models are not used to train general-purpose models.
Is Resemble AI SOC 2 or ISO 27001 certified?
Its trust center reports an ISO/IEC 27001:2022 certificate and completion of a SOC 2 Type II examination; review report scope before procurement.
How does Resemble AI compare with ElevenLabs?
For new hosted voice generation, ElevenLabs remains a direct commercial option; Resemble’s current core offering is primarily detection and media security.
Is PlayHT a current alternative?
Multiple 2026 sources report PlayHT/PlayAI shutdown or unavailable services. Check service status before considering it a new-production option.
SEO publishing package
Recommended SEO title: Resemble AI: Company Profile, Founders, Funding & AI Detection
Meta description: Explore Resemble AI’s founders, 2026 deepfake-detection pivot, products, voice-cloning history, funding, pricing, safety, customers and competitors.
Suggested URL slug: /companies/resemble-ai/
- Resemble AI: Company Profile, Founders, Funding & AI Detection
- Resemble AI Company: Voice Cloning History & Deepfake Security
- Resemble AI: Products, Pricing, Investors & Detection Models
- Resemble AI Company Profile: AI Voice Origins and 2026 Pivot
- Resemble AI: Deepfake Detection, Watermarking & Competitors
Directory description (56 words): Resemble AI is a generative voice AI pioneer founded in 2019 that now focuses on enterprise deepfake detection and synthetic-media security. Its platform offers audio, video and image verification, identity checks, watermarking and developer APIs. Resemble also maintains open-source voice-cloning research, while new paid voice-generation subscriptions are no longer offered.
Internal-link ideas, pending existence checks: Resemble AI Case Studies; Resemble AI Tool Profile; AI Voice Companies; Voice Cloning Tools; Deepfake Detection Tools; AI Audio Tools; ElevenLabs; Respeecher; Cartesia; AI Security Companies. These are recommendations, not invented live internal URLs.
Research notes & evidence limits
- Research date: 31 Oct 2026. Pricing verified against official live rates on the same date.
- Latest model announcement identified: RAD-S1, 29 Oct 2026. The press page shows a weekly watchlist dated 30 Oct 2026; that is not a new product model.
- Last quantified primary-source financing: US$13M strategic, 7 Dec 2025; US$25M cumulative stated. March 2026 secondary financing records have unspecified amounts and could not be reconciled.
- Current valuation/revenue/profit/equity: Not publicly disclosed or independently verified. No estimates are inserted.
- Corporate address: Santa Clara on LinkedIn vs Mountain View in the privacy policy. These are not silently conflated; official US mailing address is given in policy.
- AI model internals: DETECT-World’s vendor-described approach is public; complete model weights, architecture, data sources and external reproducibility are not. Resemblyzer and Chatterbox disclosures do not establish private architecture.
- Training sources: Full origin/licensing details for all historical generative-voice datasets are not publicly disclosed in sources reviewed.
- Languages: 54 is the current DETECT-World detection-language figure from MLAADv10, not the number supported by every other Resemble model.
- Benchmark caveats: Podonos Oct 2026 public leaderboard showed DETECT-World 99.47% on 4,524 clips; image 95.77% and video 98.2% are internal company figures not independently validated there. No detector is perfect.
- Customer evidence: Named official case studies are separated from third-party testimonials, awards, investors, unnamed investigations and other marketing logos.
- Compliance: Trust center reports ISO and SOC 2. Public report details may require document access; HIPAA compliance is not a product-wide government certification.
- Historical product pages: Some live voice-related pages are still accessible even though new commercial voice sales ended by Aug 2026; this article follows the CEO's explicit statement on availability.
- Unavailable verification: Exact incorporation day, cap table, patent portfolio, current COO/CTO list, standalone voice-clone commercial terms, all customer outcomes and every enterprise contract.
Editorial method: official claims, investor statements, independent evidence, and unverified information are identified separately. Research completed 31 October 2026.
Sources & references
Primary company pages are prioritized for current product and legal facts; investor sources substantiate financing and founder history; benchmark sources are separated from company claims.
Company sources
Resemble AI · Editorial team · Undated · Accessed 31 October 2026
Resemble AI · Zohaib Ahmed · 13 Aug 2026 · Accessed 31 October 2026
Resemble AI · Editorial team · Live page · Accessed 31 October 2026
Resemble AI / LinkedIn · Company profile · Live listing · Accessed 31 October 2026
Gartner Peer Insights · Editorial / listing · 20 Aug 2026 · Accessed 31 October 2026
Founders sources
Javelin Venture Partners · Investor team · 2023 · Accessed 31 October 2026
AWE USA · Conference team · 2020 · Accessed 31 October 2026
Wellfound · Company profile · Live listing · Accessed 31 October 2026
Funding sources
Resemble AI · Zohaib Ahmed · 7 Dec 2025 · Accessed 31 October 2026
Comcast Ventures · Marc Silberman & Ryan Lee · 25 Jul 2023 · Accessed 31 October 2026
TechCrunch · Kyle Wiggers · 12 Jul 2023 · Accessed 31 October 2026
McMaster University / The Forge · Editorial team · 24 Jan 2020 · Accessed 31 October 2026
Products sources
Resemble AI · Editorial team · Live page · Accessed 31 October 2026
Resemble AI · Editorial team · Live page · Accessed 31 October 2026
Resemble AI · Editorial team · Live page · Accessed 31 October 2026
Resemble AI · Editorial team · Live page · Accessed 31 October 2026
Resemble AI · Editorial team · Live page · Accessed 31 October 2026
Resemble AI · Editorial team · Live page · Accessed 31 October 2026
Resemble AI · Editorial team · Live legacy page · Accessed 31 October 2026
Models sources
Resemble AI · Editorial team · Live page · Accessed 31 October 2026
Resemble AI · Dev Shah · 29 Oct 2026 · Accessed 31 October 2026
Developers sources
Resemble AI Documentation · Developer team · Live documentation · Accessed 31 October 2026
Resemble AI Documentation · Developer team · Live documentation · Accessed 31 October 2026
Research sources
Resemble AI / GitHub · Resemble AI contributors · 2025–2026 · Accessed 31 October 2026
Resemble AI / GitHub · Resemble AI contributors · 2025–2026 · Accessed 31 October 2026
Resemble AI / GitHub · Open-source contributors · Undated · Accessed 31 October 2026
Resemble AI · Resemble AI research team · 18 May 2026 · Accessed 31 October 2026
IJCNN / arXiv · Nicolas M. Müller et al. · 2024 · Accessed 31 October 2026
Benchmarks sources
Podonos / GitHub · Podonos · Oct 2026 · Accessed 31 October 2026
Customers sources
Resemble AI · Darya Niknamian · 25 May 2026 · Accessed 31 October 2026
Resemble AI · Darya Niknamian · 2 Oct 2026 · Accessed 31 October 2026
Resemble AI · Editorial team · 11 Jul 2022 · Accessed 31 October 2026
Resemble AI · Editorial team · 25 Jul 2024 · Accessed 31 October 2026
Resemble AI · Darya Niknamian · 7 Oct 2026 · Accessed 31 October 2026
Partners sources
Resemble AI · Editorial team · 2026 · Accessed 31 October 2026
Trust sources
Resemble AI · Legal / Privacy · Updated 14 Aug 2026 · Accessed 31 October 2026
Resemble AI · Legal · Updated 14 Aug 2026 · Accessed 31 October 2026
Resemble AI / Secureframe · Trust team · Live page · Accessed 31 October 2026
Resemble AI · Editorial team · Live page · Accessed 31 October 2026
Reviews sources
G2 · Community reviewers · 2025–2026 · Accessed 31 October 2026
Trustpilot · Community reviewers · 2023–2026 · Accessed 31 October 2026
Competitors sources
ElevenLabs · ElevenLabs · Live page · Accessed 31 October 2026
Reality Defender · Reality Defender · Live page · Accessed 31 October 2026
Crail · Editorial team · 27 Jul 2026 · Accessed 31 October 2026
History sources
Resemble AI · Zohaib Ahmed · 7 Aug 2024 · Accessed 31 October 2026
Resemble AI · Zohaib Ahmed · 28 Jun 2024 · Accessed 31 October 2026