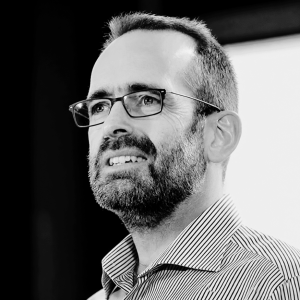
His career is unusual because it combines academic research, machine learning, bioinformatics, software engineering, international research experience, and entrepreneurship. After studying computer science at Karlsruhe University and completing his doctorate, Berthold spent several years working and researching in the United States and Australia, including at Carnegie Mellon University, UC Berkeley, and Intel. In 2003, he joined the University of Konstanz as professor and chair for Bioinformatics and Information Mining.
The KNIME project began in early 2004 at the University of Konstanz. Its founders were attempting to solve a practical problem: data scientists and researchers had increasingly complex data, but the available tools were fragmented, difficult to integrate, programming-heavy, and often difficult to reproduce.
Instead of creating another single-purpose statistical application, the team envisioned a modular, scalable and open data-processing platform where users could visually assemble analytical workflows from reusable components.
This distinction is important. KNIME was not simply a commercial product that was later released as open source. The project was designed around openness and community participation from the beginning. Its first public release, KNIME 1.0.0, arrived on July 28, 2006.
Over time, KNIME expanded from a visual data-analysis environment into a broader enterprise analytics platform covering:
- Data integration
- Data preparation
- ETL
- Machine learning
- Statistical analysis
- Visualization
- Workflow automation
- Python and R integration
- Database connectivity
- Big-data processing
- Cloud deployments
- Enterprise collaboration
- Generative AI and LLM workflows
The most important conceptual contribution of KNIME is arguably its node-and-workflow architecture. Instead of representing an analysis primarily as a script, users construct a visual workflow where each node performs a defined operation. The workflow itself becomes both the analytical process and its documentation.
KNIME's evolution also demonstrates an interesting business model: open-source software at the core, with commercial enterprise capabilities around it. The platform eventually developed enterprise products such as KNIME Server and KNIME Business Hub, while maintaining the open-source KNIME Analytics Platform.
By 2024, the research material describes KNIME as having approximately 400 enterprise customers and around €30 million in ARR, with customers including Audi, AMD, Lilly, Novartis, Bayer, Sanofi, Genentech, the FDA, P&G, and Mercedes-Benz. The company also received a $30 million investment from Invus in 2024, bringing reported total funding to approximately $50 million.
Berthold's leadership evolved alongside the company. He became full-time CEO in 2017 and stepped down from the CEO role in early 2026 after almost two decades of involvement in the company's development.
The larger story of Michael Berthold is therefore not simply "the inventor of KNIME." It is the story of an academic researcher who helped identify a structural problem in data science, assembled a technically strong team, chose openness as a strategic principle, and helped transform a university project into a commercial platform.
2. Michael R. Berthold — Quick Facts
| FieldInformation | |
| Full Name | Michael R. Berthold |
| Born | 1966, Stuttgart, Germany |
| Profession | Computer Scientist, Academic, Entrepreneur, Author |
| Academic Fields | Machine Learning, Data Mining, Bioinformatics, Computational Intelligence |
| Best Known For | Co-founding KNIME |
| Major Technology | KNIME — Konstanz Information Miner |
| Academic Institution | University of Konstanz |
| Doctoral Institution | Karlsruhe University |
| KNIME Role | Co-founder |
| CEO Role | Full-time CEO from 2017 until early 2026 |
| Major Research Areas | Data Mining, Machine Learning, Fuzzy Systems, Bioinformatics |
| Publications | 250+ publications according to the supplied research |
| Major Recognition | IEEE Fellow, KS Fu Award |
| Major Company | KNIME AG |
The supplied research identifies Berthold as a professor and chair for Bioinformatics and Information Mining at the University of Konstanz and as a major figure in data mining and machine learning.
3. Who Is Michael Berthold?
Michael R. Berthold represents a rare combination of researcher, professor, software architect, entrepreneur and technology leader.
His professional identity was formed around a central question:
How can increasingly sophisticated data analysis become easier to build, understand, reproduce and share?
Before KNIME, Berthold worked extensively on machine learning, fuzzy systems, neural networks, data mining and bioinformatics. His research was not limited to theoretical algorithms. Much of his work involved interactive analysis of complex datasets.
That practical orientation became extremely important later.
KNIME was ultimately designed around the idea that data analysis should not be trapped inside:
- isolated scripts,
- proprietary applications,
- disconnected databases,
- undocumented analytical procedures,
- or highly specialized programming environments.
Instead, the analysis should become a visible, modular process.
Berthold's academic career at Konstanz gave him an environment in which he could observe the challenges faced by researchers and companies. His industrial experience gave him an understanding of why academic prototypes often fail when they encounter real-world requirements around scalability, maintainability and integration.
This combination ultimately became one of KNIME's defining characteristics.
4. Early Life
Michael Berthold was born in 1966 in Stuttgart, Germany.
Publicly available information about his childhood and family life is limited. Therefore, claims about specific childhood influences should be treated cautiously.
The research does document an interesting academic connection: Berthold is described as the great-grandson of Prof. Gottfried Berthold, a professor of botany at Göttingen University between 1887 and 1923.
However, there is insufficient evidence to conclude that this family connection directly determined Michael Berthold's career.
What is much better documented is his later academic trajectory.
His education quickly became centered on computer science, machine learning and computational intelligence, eventually leading him toward research environments in Germany, the United States and Australia.
5. Education
Karlsruhe University
Berthold completed both his major university degrees at Karlsruhe University.
| DegreeInstitutionFieldYear | |||
| MSc | Karlsruhe University | Computer Science | 1992 |
| Dr.rer.nat. | Karlsruhe University | Computer Science | 1997 |
His doctoral research concentrated on:
- Machine learning
- Fuzzy systems
- Rule extraction
- Probabilistic neural networks
- Regression
- Fuzzy graphs
This work is significant because it was concerned not only with making models powerful but also with making analytical results understandable.
That theme—complex computation presented through understandable structures—would later appear strongly in KNIME's workflow philosophy.
6. Doctoral Research
Berthold's PhD research focused on constructive approaches to probabilistic neural networks and extracting fuzzy rule models from data.
One important direction was the development of models that could represent relationships in data in a more interpretable form.
Rather than treating machine learning simply as:
Input → Black Box → Prediction
his research explored structures that could help researchers understand the underlying relationships.
This intellectual background matters when examining KNIME.
KNIME is not itself a machine-learning algorithm. It is a platform for constructing analytical processes.
But the philosophy is related:
Complex computation → modular representation → visible analytical process
The supplied research therefore connects Berthold's earlier work in interpretable machine learning with the later usability and transparency principles embodied by KNIME.
7. International Research Career
Berthold's career became increasingly international.
| InstitutionRolePeriod | ||
| Carnegie Mellon University | Visiting Researcher | 1991 |
| University of Karlsruhe | Researcher | 1993 |
| University of Sydney | Visiting Researcher | 1994 |
| UC Berkeley | BISC Research Fellow & Lecturer | 1997–2000 |
| Intel / Industrial Think Tank | Director | ~2000–2003 |
He spent more than seven years working across academic and industrial environments outside Germany.
This experience exposed him to different approaches to:
- Computer science research
- Software development
- Industrial analytics
- Machine learning
- Data-intensive applications
- Technology commercialization
The industrial experience was especially important.
8. Intel and the Industry Perspective
Before KNIME, Berthold worked at Intel and an industrial think tank in South San Francisco.
This was a major transition.
Academia often asks:
Can this method work?
Industry asks additional questions:
Can it work reliably?
Can other people use it?
Can it scale?
Can it integrate with existing systems?
Can a business support it?
Can teams reproduce the process?
These questions would later become fundamental to KNIME.
The supplied research specifically identifies this period as important because Berthold encountered businesses struggling with the practical adoption of analytics.
9. University of Konstanz
In August 2003, Berthold became professor and chair for Bioinformatics and Information Mining at the University of Konstanz.
His research environment focused on applying computational techniques to large and complex information repositories.
Research topics included:
- Interactive clustering
- Active learning
- Hierarchical fuzzy rule systems
- Molecular graph mining
- Distributed data-mining algorithms
- High-throughput screening
- Bioinformatics
This environment became the birthplace of KNIME.
10. The Data Problem of the Early 2000s
To understand KNIME, it is necessary to understand what data science looked like around 2003–2004.
Modern users have access to:
- cloud warehouses,
- notebooks,
- APIs,
- Python libraries,
- drag-and-drop platforms,
- managed ML services,
- generative AI assistants.
The environment was very different in the early 2000s.
Data analysis frequently involved combinations of:
- statistical packages,
- SQL databases,
- custom scripts,
- spreadsheets,
- specialized scientific applications,
- visualization software,
- manually exchanged files.
The problem was not that useful tools did not exist.
The problem was fragmentation.
A researcher might need one application to load data, another to clean it, another to build a model, another to visualize it, and custom code to connect the pieces.
The result was a workflow that was difficult to understand and even harder to reproduce.
11. Five Problems KNIME Attempted to Solve
11.1 Fragmentation
Different analytical tasks required different tools.
11.2 Programming Dependency
Many advanced analytical workflows required programming skills.
11.3 Reproducibility
It was difficult to preserve exactly how an analysis had been performed.
11.4 Scalability
Data volumes were increasing rapidly.
11.5 Integration
Different data sources and analytical tools needed to work together.
The KNIME team recognized that solving these problems required more than another algorithm.
It required a platform architecture.
12. The Birth of KNIME
KNIME began in early 2004 at the University of Konstanz.
The stated objective was ambitious:
Build a modular, highly scalable and open data-processing platform capable of integrating data loading, processing, transformation, analysis and visual exploration.
The platform was deliberately designed without being restricted to a single application domain.
That decision was strategically important.
Instead of creating:
"A pharmaceutical analytics tool"
the team created:
"A general-purpose analytical workflow platform."
This allowed KNIME to expand beyond its original life-sciences environment.
13. What Does KNIME Stand For?
KNIME = Konstanz Information Miner
The name reflects both the platform's origin and its purpose.
Konstanz
The University of Konstanz was the birthplace of the project.
Information
The platform was designed to process and extract useful information.
Miner
The term "miner" reflects the broader data-mining tradition of discovering useful patterns and knowledge from data.
The name therefore communicates both academic origin and analytical purpose.
14. KNIME Was Not a Solo Invention
One of the most important corrections to the popular founder narrative is that KNIME was not created by Michael Berthold alone.
The supplied research identifies the early team as including:
- Michael Berthold
- Bernd Wiswedel
- Thomas Gabriel
- Peter and other developers
Berthold provided major scientific and strategic leadership, but the platform was developed collaboratively.
The team applied professional software-engineering practices rather than treating KNIME as a temporary academic prototype.
This distinction matters.
The correct description is:
Michael Berthold — co-founder and key scientific/strategic leader
not:
Michael Berthold — sole inventor of KNIME.
15. The First KNIME Release
KNIME 1.0.0 was publicly released on:
July 28, 2006
The original system was built using:
- Java
- Eclipse
- Modular plug-ins
- Graphical workflow editor
- Node-based processing
- Open-source licensing
The early interface was considerably less polished than today's KNIME environment.
The research material even records descriptions of the early interface as unattractive and difficult to understand.
But the underlying architecture was the important part.
The team was building a foundation that could evolve.
16. The Most Important KNIME Innovation: Nodes
The fundamental unit of KNIME is the node.
Think of a node as a specialized machine.
One node might:
- Read an Excel file
- Filter rows
- Remove missing values
- Join two datasets
- Calculate a new column
- Train a model
- Evaluate a model
- Generate a chart
- Write results to a database
Users connect nodes together.
For example:
Excel File → Cleaning → Filtering → Feature Engineering → ML Model → Evaluation → Visualization
That connected structure is the workflow.
17. What Is a KNIME Workflow?
A workflow is a structured representation of an analytical process.
At a basic level:
Data → Processing → Analysis → Visualization → Result
But the major advantage is that the workflow preserves the actual sequence of operations.
Instead of telling another analyst:
"First clean the data, then remove these columns, then join this table, then train the model..."
you can provide the workflow itself.
The analytical procedure becomes an executable object.
That is a major reason KNIME became attractive for:
- Research
- Education
- Auditing
- Enterprise analytics
- Collaboration
- Reproducible science
18. Why Visual Workflows Became So Important
The visual workflow was initially one architectural choice among many.
But it eventually became one of KNIME's strongest differentiators.
Traditional programming looks like:
Code → Execution → Result
KNIME looks like:
Visual Workflow → Execution → Result
This creates several benefits.
Visibility
Users can immediately see the sequence of operations.
Documentation
The workflow itself documents the analysis.
Reproducibility
The complete analytical process can be saved and shared.
Collaboration
A colleague can inspect the workflow without reading thousands of lines of code.
Accessibility
Users who are not expert programmers can participate in advanced analytics.
Berthold later acknowledged that he did not initially anticipate how influential the visual workflow editor would become.
19. KNIME vs Traditional Coding
| Traditional CodingKNIME | |
| Workflow exists primarily in code | Workflow visible on canvas |
| Programming skills required | Visual construction |
| Documentation often separate | Workflow itself documents process |
| Reproduction requires code/environment | Workflow can be shared |
| Debugging through code | Node-level inspection |
| Integration often manually coded | Connectors and nodes |
| High flexibility | Visual + code flexibility |
However, KNIME should not be understood as a replacement for programming.
One of its important strengths is that it can combine visual workflows with:
- Python
- R
- SQL
- Java
- APIs
- External libraries
Therefore, KNIME is better described as a visual low-code/high-code hybrid analytics environment.
20. KNIME's Open-Source Philosophy
Open source was not an accidental business decision.
The team deliberately selected an open-source strategy because it wanted to create a community around the platform.
The supplied research emphasizes three major motivations:
Community
A healthy community can expand faster around an open platform.
Innovation
External developers can build extensions and integrations.
Freedom
Users are less dependent on a single proprietary vendor.
This was an unusual strategy for an enterprise analytics company.
Instead of saying:
Pay first, then access the platform.
KNIME's philosophy was closer to:
Use the platform, build with it, contribute to it, and pay when you need enterprise capabilities.
21. The Open-Core Business Model
This created an important economic challenge.
If the core platform is open source, how does the company make money?
KNIME's answer was open core + enterprise products.
The broader model includes:
- Open-source KNIME Analytics Platform
- Enterprise deployment
- KNIME Server
- KNIME Business Hub
- Cloud services
- Training
- Consulting
- Partnerships
This allowed KNIME to separate:
Community adoption
from
Enterprise monetization
That became one of the company's most important strategic decisions.
22. University to Company
KNIME began as a university project.
But eventually the scale of work required a dedicated company.
The transition can be represented as:
University Research
↓
Open-Source Project
↓
Growing User Community
↓
Enterprise Requirements
↓
Commercial Company
↓
Enterprise Analytics Platform
The supplied research notes that eventually the work involved responsibilities that were no longer appropriate for a purely academic research group.
Those responsibilities included:
- Enterprise support
- Product development
- Server infrastructure
- Customer relationships
- Commercial scaling
23. The Company
The supplied research contains a discrepancy regarding the exact company-formation year, citing both 2006 and 2008 in different source contexts.
Therefore, the safest framing is:
KNIME transitioned from its University of Konstanz origins into a commercial company during the 2006–2008 period.
This is an example of an area where the supplied research itself identifies conflicting information and should not be artificially reconciled.
24. Michael Berthold as CEO
Berthold eventually moved from primarily academic leadership toward full-time company leadership.
In 2017, he became full-time CEO and moved to Zurich.
This marked a major shift.
His responsibilities expanded from:
Research + academic leadership
to:
Product + company + customers + strategy + fundraising + community + enterprise growth
He continued to maintain his academic association with the University of Konstanz, creating a rare dual identity between university research and technology entrepreneurship.
25. KNIME's Technology Evolution
| PeriodEvolution | |
| 2004–2006 | Research platform |
| 2006–2010 | Open-source analytics platform |
| 2010–2016 | Data science and ML platform |
| 2016–2020 | Enterprise analytics |
| 2020–Present | Cloud + AI + enterprise analytics |
The underlying philosophy remained relatively consistent:
Open + Modular + Visual + Extensible
The capabilities around that foundation changed dramatically.
26. KNIME Ecosystem
The KNIME ecosystem expanded beyond a single desktop application.
KNIME Analytics Platform
The open-source analytical environment.
KNIME Server
Enterprise workflow execution and management.
KNIME Business Hub
Enterprise collaboration, deployment and workflow management.
KNIME Community Hub
A community environment for discovering and sharing workflows and components.
The ecosystem also includes extensions for:
- Machine learning
- Deep learning
- Databases
- Cloud
- Big data
- Python
- R
- Text analytics
- Visualization
- APIs
27. Machine Learning Capabilities
KNIME supports a broad machine-learning workflow.
Classification
- Decision trees
- Random forests
- SVM
- Logistic regression
- Neural networks
Regression
- Linear regression
- Polynomial regression
- Generalized linear models
Clustering
- K-means
- DBSCAN
- Hierarchical clustering
Feature Engineering
- Feature selection
- PCA
- Transformation
- Encoding
Evaluation
- Cross-validation
- Confusion matrices
- ROC curves
- Accuracy
- Precision
- Recall
- Other metrics
Deep Learning
Integrations with frameworks such as TensorFlow and Keras.
The major advantage is that the complete ML process can exist inside one visual workflow.
28. KNIME and Generative AI
KNIME's AI evolution reflects the broader transformation of analytics.
Traditional analytics asks:
What happened?
Machine learning asks:
What is likely to happen?
Generative AI increasingly asks:
Can the system help me build the analytical process itself?
The supplied research identifies KNIME's AI strategy as including:
- AI assistant capabilities
- LLM integrations
- Text processing
- Summarization
- Retrieval-augmented generation
- Enterprise AI governance
- Model monitoring
- AI workflow development
The AI assistant is particularly significant because it potentially reduces the effort required to create or extend workflows.
29. Why KNIME's AI Strategy Matters
AI could potentially weaken traditional analytics platforms.
Why?
Because modern AI tools can generate:
- Python
- SQL
- Data transformations
- Charts
- Models
- Documentation
- Analytical explanations
That creates a strategic challenge for visual analytics platforms.
KNIME's response is not to abandon workflows.
Instead, it is increasingly combining:
Visual workflows + traditional analytics + Python/R + LLMs + AI assistance
This creates a hybrid environment in which AI becomes another component inside the analytical workflow.
30. Data Integration
One of KNIME's strongest capabilities is integration.
It can connect with:
Files
- Excel
- CSV
- JSON
- Parquet
Databases
- SQL databases
- Enterprise databases
- JDBC/ODBC sources
Programming
- Python
- R
- Java
Cloud
- AWS
- Azure
- Google Cloud
Big Data
- Hadoop
- Spark
APIs
- REST APIs
- Web services
The broader philosophy is not merely data blending.
It is tool blending.
That distinction is important.
KNIME attempts to bring different analytical technologies into a common workflow environment.
31. Why Tool Blending Matters
A modern analytics project might involve:
SQL → Python → Machine Learning → LLM → Visualization → Cloud Database
Without an integration platform, each stage can become a separate technical environment.
KNIME attempts to connect those stages visually.
That makes the workflow something like:
Database Node
↓
Data Cleaning Node
↓
Python Node
↓
ML Node
↓
LLM Node
↓
Visualization
↓
Database / Dashboard
The analytical workflow becomes an integrated system rather than a collection of disconnected tools.
32. Real-World Industry Applications
KNIME has been used across many industries.
Life Sciences
- Drug discovery
- Genomics
- Clinical data
- Research analytics
- High-throughput screening
Financial Services
- Risk analysis
- Fraud detection
- Customer analytics
- Predictive modeling
Manufacturing
- Predictive maintenance
- Quality analysis
- Process optimization
Retail
- Customer segmentation
- Pricing
- Supply chain
- Marketing analytics
Government
- Regulatory analytics
- Public data
- Scientific analysis
Consulting
- Client analytics
- Data preparation
- Automated reporting
The life-sciences sector was especially important in KNIME's early growth because researchers there were already dealing with large and complex datasets before "big data" became a mainstream business term.
33. Major Customers
The supplied research identifies major organizations associated with KNIME, including:
- Audi
- AMD
- Lilly
- Novartis
- Bayer
- Sanofi
- Genentech
- FDA
- P&G
- Mercedes-Benz
These examples demonstrate that KNIME moved beyond academic and scientific users into mainstream enterprise environments.
34. Business Model
KNIME's commercial model can be summarized as:
Free/Open Core → Community Adoption → Enterprise Monetization
Revenue sources include:
- Enterprise subscriptions
- Cloud offerings
- Training
- Services
- Partnerships
The model is strategically interesting because the free product functions not simply as a cost center but also as an adoption engine.
Users can discover KNIME without negotiating a large enterprise contract.
Organizations can later pay when they need:
- Governance
- Deployment
- Collaboration
- Central management
- Enterprise support
- Cloud capabilities
35. Funding
The supplied research reports:
2024 — $30 million investment from Invus
and approximately:
$50 million total funding
The investment was intended to support areas such as:
- Product development
- Team expansion
- Cloud strategy
- AI
- Commercial growth
36. Business Scale
According to the supplied research, KNIME had approximately:
- 400 enterprise customers
- ~€30 million ARR
- 250 employees
- 30–40% annual ARR growth
- Customers in 60+ countries
These figures are primarily associated with the 2024 period and should not automatically be interpreted as exact 2026 numbers.
37. Competitive Landscape
KNIME operates in a crowded analytics market.
Major competitive categories include:
Alteryx
Strong visual analytics and enterprise adoption.
Dataiku
Enterprise data science and AI collaboration.
SAS
Enterprise-grade statistical and analytical capabilities.
IBM SPSS
Traditional statistical analytics.
RapidMiner
Visual data science.
Python Ecosystem
Maximum flexibility and enormous developer ecosystem.
Databricks
Lakehouse, data engineering and AI.
Power BI / Tableau
Business intelligence and visualization.
KNIME's strategic position is unusual because it combines:
Visual analytics + open source + enterprise features + integrations + workflow reproducibility.
38. KNIME vs Alteryx
| KNIMEAlteryx | |
| Open-source core | Proprietary |
| Visual workflows | Visual workflows |
| Large community | Commercial ecosystem |
| Strong integrations | Strong integrations |
| Enterprise products | Enterprise products |
| Lower barrier to experimentation | Commercial licensing |
| Open-source philosophy | Proprietary business model |
The philosophical difference is especially important.
Alteryx primarily monetizes the software itself.
KNIME uses open source as a mechanism for adoption and community development, then monetizes enterprise capabilities.
39. KNIME vs Python
This is not necessarily an either/or decision.
Python offers:
- Maximum flexibility
- Huge ecosystem
- Developer control
- Advanced AI/ML libraries
KNIME offers:
- Visual workflows
- Easier workflow inspection
- Lower programming barrier
- Integration
- Reproducibility
- Enterprise workflow management
The strongest practical model can actually be:
KNIME + Python
rather than:
KNIME vs Python
The platform's ability to integrate Python is therefore strategically important.
40. Competitive Advantages
The supplied research identifies several major advantages.
1. Open Source
Users can access the platform without traditional proprietary software restrictions.
2. Visual Workflow
The workflow is the actual analytical process.
3. Integration
KNIME connects data sources and analytical technologies.
4. Community
External contributions expand the ecosystem.
5. Professional Architecture
The platform was designed for scalability from the beginning.
6. Academic Credibility
Its research heritage provides strong credibility among technical users.
7. Enterprise Capability
The platform evolved beyond research into enterprise deployment.
41. Intellectual Property
The supplied research does not identify specific patents belonging to Michael Berthold or KNIME.
Therefore, patent-related claims should not be overstated.
KNIME's principal intellectual-property assets are better understood as:
- Software code
- Copyright
- KNIME trademark and brand
- Software architecture
- Community ecosystem
- Workflow technology
- Enterprise products
- Know-how
The company's competitive strategy has historically emphasized open software and community participation, rather than patents as the primary moat.
42. Awards and Recognition
Berthold's academic career includes significant recognition.
The supplied research identifies:
- IEEE Fellow
- KS Fu Award
- Honorary Professor at Óbuda University
- Past President of IEEE Systems, Man, and Cybernetics Society
- Past President of the North American Fuzzy Information Processing Society
These recognitions reinforce that his career predates and extends beyond KNIME.
43. Academic Impact
KNIME has become useful in education and research because it makes analytical workflows easier to visualize and share.
Potential academic benefits include:
Teaching
Students can learn analytical concepts without initially mastering large amounts of code.
Research
Scientists can preserve analytical workflows.
Reproducibility
Other researchers can inspect the process.
Collaboration
Workflows can be shared.
Open Science
Open tools support transparency and reuse.
This creates an important connection between Berthold's academic identity and KNIME's commercial success.
44. Industry Impact
KNIME contributed to several broader trends.
Democratization of Data Science
Sophisticated analytics became accessible to more users.
Low-Code Analytics
Users could construct workflows without writing every operation manually.
Reproducibility
The workflow became a record of the analytical process.
Tool Integration
Different technologies could coexist in one workflow.
Open-Source Enterprise Software
KNIME demonstrated that an open-source core could support a commercial company.
45. Challenges
KNIME's journey was not without challenges.
Academic → Commercial Transition
A university project and a global enterprise require very different operating models.
Open-Source Monetization
The company had to prove that free software could support a sustainable business.
Enterprise Adoption
Large customers require governance, support, deployment and security.
Cloud
Cloud-native competitors changed expectations around deployment.
AI
Generative AI potentially changes how analytical workflows are created.
Competition
KNIME competes against both traditional analytics companies and new AI/data platforms.
46. Failures and Mistakes
Public information about major KNIME failures is limited.
However, several lessons emerge.
Underestimating Visual Workflows
Berthold reportedly did not initially expect the visual workflow editor to have such a major impact.
Early UI
The original interface was functional but not particularly attractive.
Commercial Sales Cycles
The company experienced longer sales cycles and more difficult negotiations during periods of technology-market slowdown.
These are less examples of catastrophic failure and more examples of learning during scale-up.
47. Open-Source Strategy — Deep Analysis
KNIME's open-source strategy can be understood through a flywheel:
Free Access
↓
More Users
↓
More Workflows
↓
More Community Contributors
↓
More Extensions
↓
More Use Cases
↓
More Enterprise Adoption
↓
More Commercial Revenue
↓
More Product Investment
↓
Better Platform
↓
More Users
This is the strategic engine behind the model.
The important point is that open source is not merely a pricing strategy.
It is a distribution and ecosystem strategy.
48. Why Community Matters
A proprietary company has a finite development team.
An open platform can attract contributions from:
- Developers
- Universities
- Consultants
- Technology vendors
- Independent data scientists
- Enterprise users
The supplied research attributes hundreds of thousands of lines of additional community code to this ecosystem.
The result is a broader innovation surface than one company could realistically build alone.
49. The KNIME Flywheel
A simplified strategic model looks like this:
Stage 1
Open-source software attracts users.
Stage 2
Users create workflows.
Stage 3
The community creates extensions.
Stage 4
The ecosystem becomes more valuable.
Stage 5
Enterprises adopt KNIME.
Stage 6
Enterprises purchase commercial capabilities.
Stage 7
Revenue funds further development.
This is one of the strongest strategic insights from KNIME's history.
50. SWOT Analysis
Strengths
- Open-source core
- Strong community
- Visual workflows
- Broad integrations
- Enterprise customer base
- Academic credibility
- Professional architecture
- Reproducibility
- Low-code accessibility
Weaknesses
- GPLv3 considerations
- Cloud maturity relative to some major competitors
- Historical perception as an academic tool
- Lower brand visibility in some markets
Opportunities
- Generative AI
- AI agents
- Cloud/SaaS
- SME adoption
- Low-code analytics
- International expansion
- Enterprise automation
Threats
- Databricks
- Dataiku
- Alteryx
- Cloud platforms
- AI-native analytics tools
- Longer enterprise sales cycles
- Competition for technical talent
51. Business Model Canvas
| ComponentKNIME | |
| Customer Segments | Data scientists, analysts, business users, enterprises, SMEs |
| Value Proposition | Open-source visual analytics with enterprise scalability |
| Channels | Website, community, partners, conferences, direct sales |
| Customer Relationships | Community, documentation, support, training |
| Revenue Streams | Enterprise subscriptions, cloud, training, services |
| Key Resources | Software, community, employees, research relationships |
| Key Activities | Product development, ecosystem management, sales |
| Key Partners | Cloud providers, consultants, universities |
| Cost Structure | R&D, sales, marketing, infrastructure, support |
52. Why KNIME Survived
Many academic software projects disappear.
KNIME did not.
Several factors explain this.
It solved a real problem
The platform addressed genuine data-analysis pain points.
It was designed professionally
The team treated it as software infrastructure rather than a temporary research prototype.
It was open
Users could adopt it without the same barriers associated with proprietary platforms.
It was extensible
The architecture allowed new capabilities to be added.
It was visually understandable
The workflow model made complex analytical processes easier to communicate.
It evolved
KNIME moved from analytics to machine learning, enterprise workflows, cloud and AI.
53. Why the Visual Model Was a Strategic Moat
Many companies can copy individual features.
It is much harder to replicate an entire ecosystem around a workflow model.
KNIME's workflow representation affects:
- User experience
- Architecture
- Collaboration
- Documentation
- Reproducibility
- Extensions
- Enterprise deployment
This creates a deeper product identity than simply having drag-and-drop nodes.
The real differentiator is:
The visual workflow is not just the interface. It represents the computational process.
That distinction has been highlighted by Berthold in interviews.
54. KNIME and Reproducible Data Science
Reproducibility is one of KNIME's most important contributions.
Imagine two analysts.
Analyst A says:
"I cleaned the data and trained a model."
Analyst B needs to know:
- Which columns were removed?
- Which values were replaced?
- Which filters were applied?
- Which algorithm was used?
- Which parameters were selected?
- Which data source was used?
- What happened before training?
In a traditional workflow, these details may be scattered across:
- scripts,
- notebooks,
- emails,
- documentation,
- spreadsheets.
In KNIME, much of that logic can exist directly in the workflow.
This makes the workflow a kind of analytical blueprint.
55. KNIME and Democratization
One of Berthold's larger contributions is the idea that data science should not belong exclusively to programmers.
A domain expert may understand:
- Chemistry
- Biology
- Finance
- Manufacturing
- Marketing
but may not be an expert Python programmer.
KNIME allows that expert to participate in analytical work through visual components.
At the same time, advanced users can introduce Python, R and custom code.
This creates a bridge between:
Domain Expertise
and
Technical Expertise
56. The Academic–Industry Bridge
Berthold's career provides a useful case study in technology transfer.
The path was:
Academic Research
↓
Real-World Problem
↓
Software Platform
↓
Open-Source Community
↓
Commercial Enterprise
This demonstrates that commercialization does not necessarily require abandoning academic principles.
KNIME retained:
- Openness
- Research orientation
- Community
- Education
- Scientific users
while adding:
- Enterprise products
- Commercial support
- Cloud
- Business development
- Customer success
57. Michael Berthold's Leadership Philosophy
The supplied interviews and research suggest several recurring principles.
Openness
Technology should not be unnecessarily locked behind proprietary barriers.
Community
A large community can innovate beyond the limits of one company.
Practicality
Research should eventually produce usable technology.
Integration
Users should not have to abandon existing tools.
Scalability
Professional software architecture matters from the beginning.
Democratization
More people should be able to work with advanced analytics.
58. The Founder Myth vs Reality
| Popular ClaimMore Accurate Reality | |
| Berthold invented KNIME alone | KNIME was a founding-team effort |
| KNIME began as a startup | It originated at University of Konstanz |
| KNIME was commercial first | It was open source from the beginning |
| KNIME is a no-code tool | It supports low-code, code and integrations |
| KNIME is only ML | It covers data engineering, analytics and AI |
| Open source means no business | KNIME developed an enterprise business |
| KNIME is academic software | It serves major enterprises |
| Visual workflows are just UI | The workflow represents computation |
59. Complete Career Timeline
| YearEvent | |
| 1966 | Born in Stuttgart |
| 1991 | Visiting Researcher, Carnegie Mellon |
| 1992 | MSc, Karlsruhe University |
| 1993 | Researcher, University of Karlsruhe |
| 1994 | Visiting Researcher, University of Sydney |
| 1997 | PhD, Karlsruhe University |
| 1997–2000 | UC Berkeley |
| ~2000–2003 | Intel / industrial think tank |
| 2003 | Professor at University of Konstanz |
| Early 2004 | KNIME project begins |
| 2006 | KNIME 1.0 released |
| 2006–2008 | Commercial company transition |
| 2010 | Guide to Intelligent Data Analysis |
| 2017 | Full-time KNIME CEO |
| 2024 | $30M Invus investment |
| Early 2026 | Steps down as CEO |
60. 20-Year Evolution of KNIME
2004
The problem is identified.
2005
Research and interactive data-mining work develops around the emerging platform.
2006
KNIME becomes publicly available.
2007–2010
Community adoption expands.
2010–2015
Machine learning and data science capabilities broaden.
2015–2020
Enterprise adoption accelerates.
2020–2023
Cloud and modern analytics become increasingly important.
2024
Major investment supports further growth and AI/cloud strategy.
2025–2026
Generative AI becomes a larger part of the product direction and leadership transition occurs.
61. Current Strategic Position
The supplied research describes KNIME's strategic position around early 2026 as:
Open-source analytics core + enterprise platform + cloud + AI
Its major strategic priorities include:
- Cloud expansion
- AI integration
- Enterprise adoption
- Community growth
- Workflow automation
- Broader accessibility
- Integration with modern data infrastructure
The biggest question for KNIME's future is whether its workflow-centric model can remain highly relevant as AI increasingly generates analytical code and workflows automatically.
62. The Biggest Strategic Question for KNIME
The next phase of analytics may look like:
"Tell the AI what you want."
rather than:
"Build the workflow yourself."
This creates both a threat and an opportunity.
Threat
AI coding assistants can generate Python, SQL and analytical pipelines.
Opportunity
KNIME can make AI itself part of the workflow.
That creates a future model:
Human Intent → AI Assistant → KNIME Workflow → Data → Model → Result
If successful, KNIME's visual workflow could become not just a tool for humans but also a structured environment in which AI-generated analytical processes can be inspected, governed and executed.
63. Future Opportunities
AI Agents
AI agents could dynamically construct and execute workflows.
Automated Data Preparation
AI could identify missing values, anomalies and transformation requirements.
Natural-Language Analytics
Users could describe the desired analysis in plain language.
Enterprise AI Governance
KNIME could provide structured workflows around AI systems.
Cloud Analytics
Cloud-native workflow execution can expand enterprise adoption.
Education
Visual analytics remains attractive for teaching data science.
SME Market
Simplified pricing and cloud deployment could expand the customer base.
64. Future Threats
The most serious threat may not be another visual analytics company.
It may be the combination of:
Databricks + Cloud + Python + AI Coding Assistants + LLMs
These technologies increasingly allow companies to build analytical pipelines without traditional workflow software.
KNIME therefore needs to prove that its platform provides something AI-generated code alone cannot easily provide:
- Governance
- Reproducibility
- Collaboration
- Visual understanding
- Enterprise deployment
- Integration
- Workflow management
- Auditability
65. Michael Berthold's Legacy
Berthold's legacy extends beyond the creation of a software company.
In Machine Learning
He contributed to fuzzy systems, neural networks and interactive machine learning.
In Data Mining
He advanced practical and interactive approaches to discovering information from large datasets.
In Scientific Software
He demonstrated how research-oriented software could become professional infrastructure.
In Open Source
He demonstrated that open-source analytics could support a commercial enterprise.
In Data Science
He helped popularize visual, reproducible workflows.
In Entrepreneurship
He demonstrated a path from university research to global technology company.
66. The Most Important Lessons From KNIME
Lesson 1 — Solve a structural problem
KNIME did not start by asking:
"What feature should we build?"
It addressed a larger problem:
"Why is data analysis so fragmented?"
Lesson 2 — Architecture matters
The team's decision to create a modular platform was more important than any individual feature.
Lesson 3 — Open source can be strategic
Open source can function as distribution, community development and ecosystem creation.
Lesson 4 — Visual design can become infrastructure
The workflow was not merely UI decoration.
It became the representation of computation.
Lesson 5 — Academic research can become enterprise technology
The university environment did not prevent commercialization.
Lesson 6 — Integration beats isolation
Modern analytics requires multiple tools.
Lesson 7 — Platforms must evolve
KNIME continuously expanded into ML, enterprise analytics, cloud and AI.
67. The KNIME Story in One Sentence
Michael Berthold and his team transformed a university effort to make data analysis modular and reproducible into an open-source analytics ecosystem that connected visual workflows, machine learning, data integration, enterprise analytics and emerging AI.
68. The KNIME Story in One Diagram
Academic Research
↓
Machine Learning + Bioinformatics
↓
Real-World Data Problems
↓
University of Konstanz
↓
KNIME Project — 2004
↓
Open Source — 2006
↓
Community
↓
Enterprise Adoption
↓
Commercial Company
↓
KNIME Server / Business Hub
↓
Cloud
↓
Generative AI
↓
AI-Assisted Data Science
69. Final Assessment
Michael Berthold should not be understood simply as the "inventor of KNIME."
A more accurate description is:
He was the scientific and entrepreneurial leader behind a collaborative team that recognized the need for a modular, open, visual data-analysis platform and successfully transformed that concept into a global enterprise technology ecosystem.
His most important contribution may not be any single algorithm.
It is the combination of:
Research + Architecture + Open Source + Visual Analytics + Community + Entrepreneurship
That combination allowed KNIME to survive for more than two decades while the data landscape changed from traditional statistical computing to machine learning, big data, cloud analytics and generative AI.
The deeper lesson of KNIME is therefore not merely about software.
It is about how a technical idea can become a platform.
A university project became open source.
Open source became a community.
The community became an ecosystem.
The ecosystem attracted enterprises.
Enterprise adoption created a business.
And the business continued evolving toward cloud and AI.
That is the real story of Michael Berthold and KNIME.
70. Research Confidence & Source Limitations
The supplied research categorizes several findings by confidence.
High Confidence
- KNIME began in early 2004 at University of Konstanz.
- First public release was July 28, 2006.
- Berthold was a co-founder.
- Bernd Wiswedel and Thomas Gabriel were part of the founding team.
- KNIME was open source from the beginning.
- Berthold is a professor, computer scientist and entrepreneur.
- 400 enterprise customers and ~€30M ARR were reported for 2024.
- $30M Invus investment and approximately $50M total funding were reported.
Medium Confidence
- Detailed composition of the earliest team beyond the principal founders.
- Exact internal growth metrics.
- Complete publication history.
- Certain operational/company-history details.
Low Confidence
- Childhood details.
- Specific early personal influences.
- Patent claims.
Conflicting Information
The supplied research itself identifies discrepancies around:
- Exact company incorporation/founding year: 2006 vs 2008.
- Exact CEO-tenure wording in different sources.
These should remain explicitly qualified rather than presented as settled facts.
71. Core Sources Referenced in the Research
The supplied research identifies the following source categories:
- KNIME official open-source history
- KNIME official blog and anniversary material
- TechCrunch coverage of the 2024 funding
- KDnuggets interview with Michael Berthold
- University of Konstanz academic profile
- MarketScreener
- DBpedia
- Wikipedia
- Bioinformatics research profiles
- Academic publications and conference biographies
The strongest claims in this report are grounded primarily in the supplied research material and its cited primary/industry sources. Where the supplied material itself flags uncertainty, the uncertainty has been preserved rather than silently corrected.